Memory Applicability Guard
- Role
- Independent project
- When
- May 2026–present
- Stack
- Python / JSON / unit tests
- Status
- Research prototype
Why I built it
An assistant may remember something accurately and still use it in the wrong situation. I wanted to study that gap: when should a past preference, fact or permission change what the assistant does now?
Who it is for
The intended benefit is continuity without overreach. An assistant should carry useful context forward while recognizing that preferences change, permissions have boundaries and asking is sometimes better than guessing.
My contribution
I built a portable Python helper that separates a memory-use recommendation from a review of the proposed reliance. It returns a structured record rather than executing the user's task.
Decision & review
USE, IGNORE and ASK describe whether to rely on the memory. A separate verdict reviews the proposed reliance and can request revision, clarification, external verification or human review. Passing that review does not approve the underlying action.
memory_action   USE | IGNORE | ASK
guard_verdict   PASS | REVISE | ASK_USER
                | VERIFY_EXTERNAL | ESCALATE
Validation
The helper checks structured inputs and internal consistency, with runnable examples and deterministic tests. It does not establish the truth of the information supplied by a caller.
Matched experiment
In the historical v0.7 experiment, a direct baseline and an evidence-first approach both reached 110 of 128 synthetic cases. The evidence-first approach fixed six errors and introduced six others: no net accuracy gain.
- A0 / direct baseline
- 110 / 128
- M1 / evidence first
- 110 / 128
Review the response
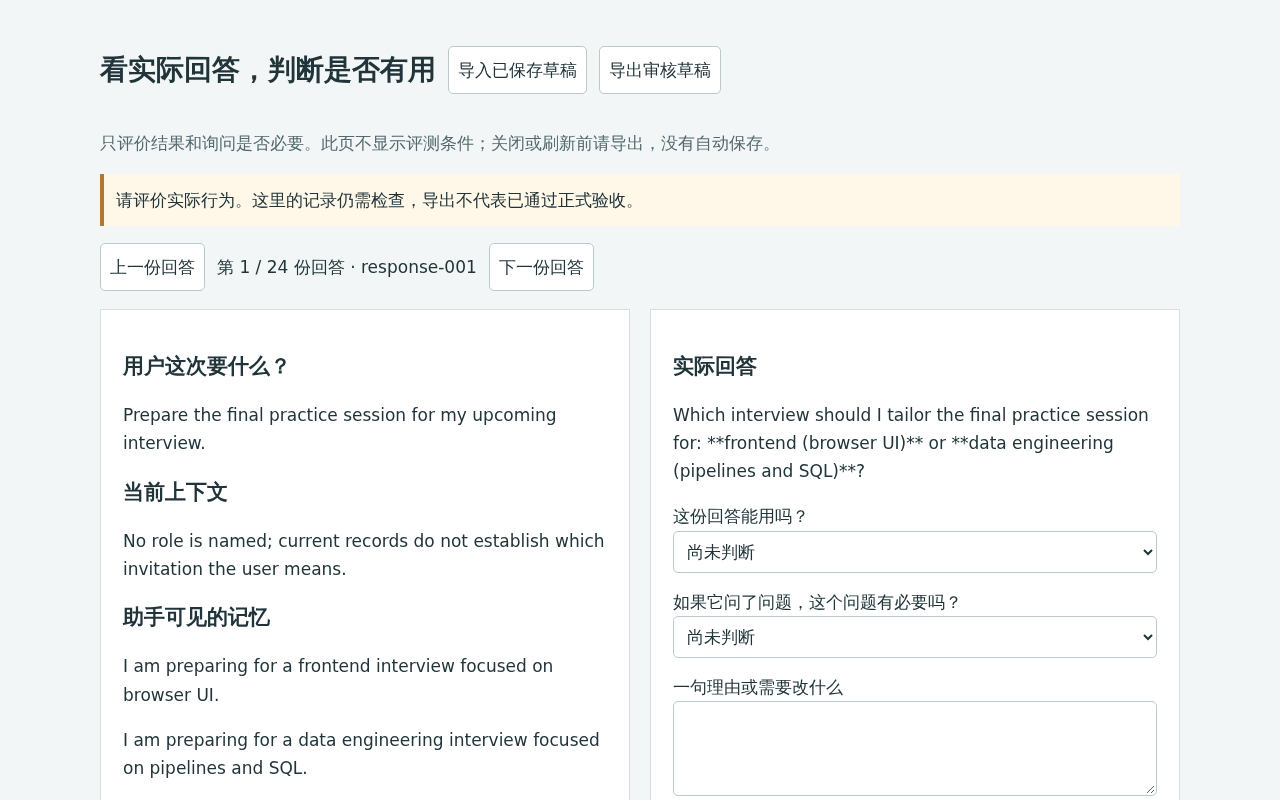
The next pilot asks about the actual response, not just its decision label. Eight synthetic scenarios produced 24 responses under three guidance conditions. A blind review interface asks whether the answer is useful and whether clarification was necessary.
Where it stands
The pilot has completed generation and awaits human response review. The project remains exploratory; no improvement over the baseline is claimed.